Recently one of the client from United Kingdom (UK) requested to scrape data from website which was showing basic details on web page and then having link to vCard file. vCard file having rest of details like Contact Name, Website, Email and Phone number.
Problem: Scraping Data From vCard Files Using Web Scraping Tools
I tried some of the third-party web scraping software to see if any of them can scrape data from vCard files but unfortunately none of them worked. I then decided to download all vCard files locally and then planned to parse content using either PHP or Python.
Solution: Parsing Downloaded vCard Files Using Python
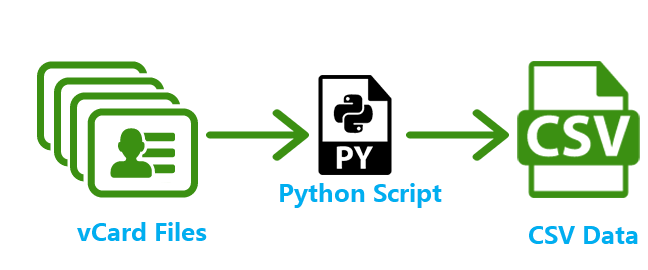
So at the end I made python script to read all the downloaded vCard files inside script and parse data and store into CSV.
Here is the code to parse contact details from vcard files:
import urllib2
import os
import csv
def get_data(csv_write,url):
	data=""
	print url
	try:
		data=urllib2.urlopen(url).read()
	except:
		pass
	email=""
	name=""
	website=""
        # Parsing email, name and website from vCard
	try:
		for str in data.split('\n'):
			if(str.find("FN:")>=0):
				name=str.replace("FN:","")
			if(str.find("URL;WORK:")>=0):
				website=str.replace("URL;WORK:","")
			if(str.find("EMAIL;TYPE=INTERNET;TYPE=PREF:")>=0):
				email=str.replace("EMAIL;TYPE=INTERNET;TYPE=PREF:","")
	except:
		pass
	csv_write.writerow([name,email,website])
if __name__=="__main__":
	input_file_name=raw_input("Enter the Linkedin URL file (.txt) : ")
	output_file_name=raw_input("Enter the output file (.csv) extention : ")
	try:
		f=open(input_file_name,"rb")
		lines=f.read().splitlines()
		f.close()

                #storing data to csv file
		output = open(output_file_name, 'vcarddata')
		writer = csv.writer(output, dialect=csv.excel, quoting=csv.QUOTE_ALL)
		row=["Name","Email","Website"]
		writer.writerow(row)

		for url in lines:
			get_data(writer,url)

	except Exception,e:
		print e
		pass
Final Thoughts
Hope you guys will enjoy this vCard parser which will do vcard to csv conversion job!
